Learn how AI inference works, the metrics that matter, and where it runs in production.
AI is now part of everyday tools, from speech-to-text and image generation to fraud detection and customer service agents. Every one of those responses comes from inference.
AI inference is the stage where a trained model is put to work. It is a core part of MLOps, the practice of bringing machine learning (ML) models into production and keeping them running reliably. It is the model's moment of truth: how well can it apply what it learned in training to data it has never seen?
Will it flag a spam email correctly, or let it land in your inbox? That depends on how well the model was trained and how well it runs at inference.
What is AI inference?
AI inference is the process of running a trained machine learning model on new data to produce an output, such as a prediction, a classification, or generated text. Training is where a model learns. Inference is where that model is used in production.
Before a model can run inference, it has to learn from large datasets, finding the patterns and relationships that enable it to make predictions. Historically, that meant labeled data. A vehicle recognition model, for example, learned to identify car make and model from labeled images of cars, using features such as shape and size. Most large language models (LLMS) in production today are pretrained on large unlabeled datasets and then adapted through fine-tuning.
Inference is often called the "action phase" of AI, where models apply what they learned to real-world scenarios.
AI inference vs. training
The machine learning life cycle includes two main phases. They are closely linked, but they serve different purposes:
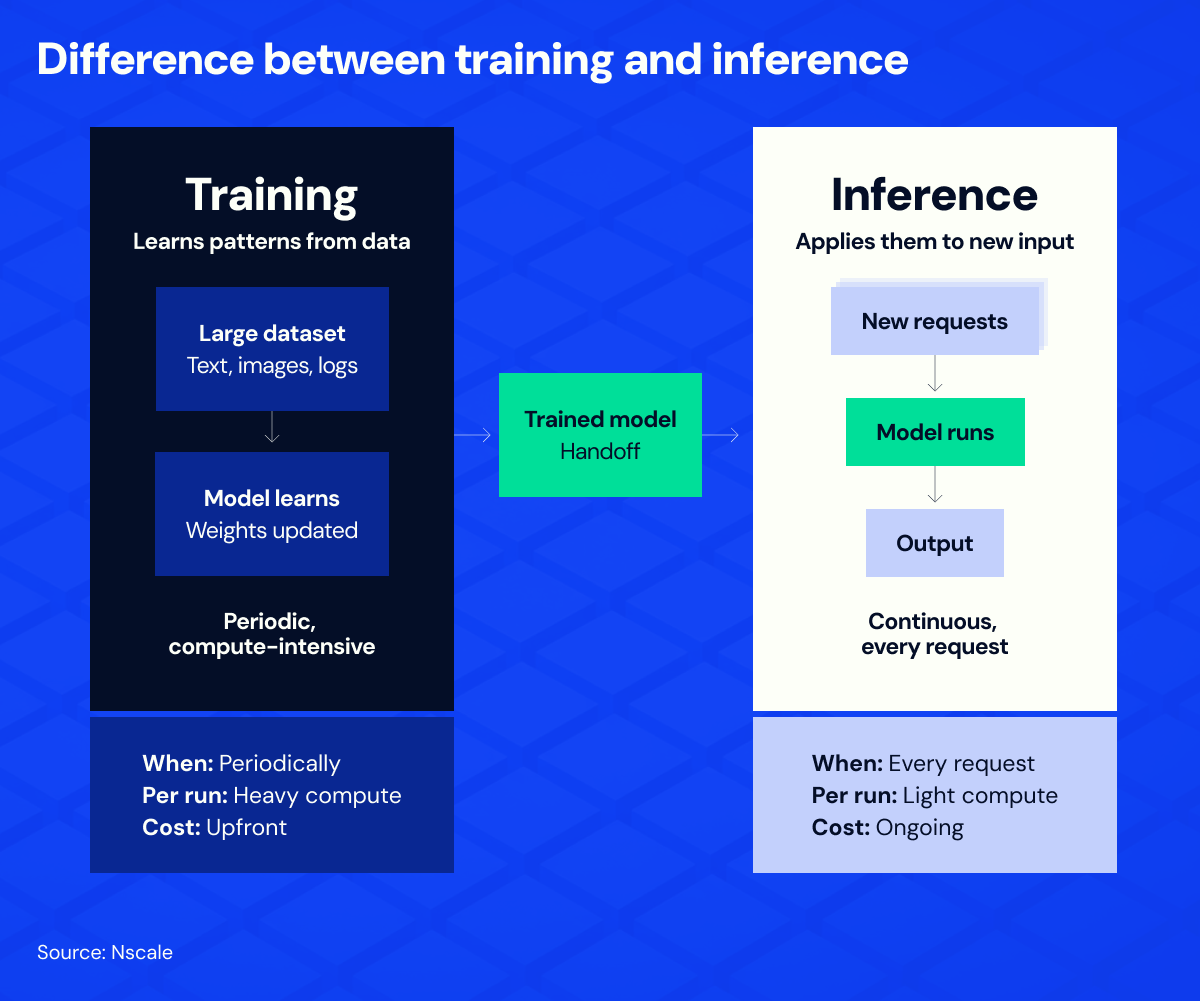
- Training: The model learns patterns from data. In classic supervised learning, the dataset is typically split into training and test data, often 70/30 or 80/20, so the model can be validated on data it has not seen.
- Inference: The trained ML model applies its knowledge to live, unseen data to produce outputs.
Think of it as the difference between learning a skill and using it. Training is compute-intensive and time-consuming, and it happens periodically. Each inference request is far lighter, but inference runs continuously, every time a user or system calls the model. At production scale, that makes inference an ongoing infrastructure cost.
How does AI inference work?
A simple inference pipeline has three steps:
- User Input/request: A user or system sends data (for example, a prompt or an image) to the model to perform a task or a prediction.
- Processing: The ML model’s host system (in the cloud or on-premises) receives the input data and passes it into the ML model, which is run by an inference engine.
- Output: The model applies the model weights to the input data to generate the predicted output or response.
What is an inference engine?
An inference engine is a specialized computing environment that is specifically designed to host and run ML model inference. The inference engine works by accepting the input data from the data source and passing it into a trained ML model, returning the inference output. These engines can run on-premises, in data centers or cloud environments.
Inference engines require ML models to be exported in a format the engine can read. Several formats are in common use, including Hugging Face Safetensors. A good overview of the different formats can be found here.
Common AI inference metrics
Common AI inference metrics for measuring inference performance include::
- Latency: The speed at which an ML model can return a complete response. Latency depends on how much compute resource is available for a specific task, how fine-tuned a model is and how optimized it is for that particular task. In an ideal world, your inference latency is always close to zero and is typically measured in milliseconds (ms).
- Throughput: The number of requests or predictions an ML model can handle in a given period. In an ideal world, your throughput should be as high as possible and is typically measured in predictions per second (PPS), requests per second (RPS) and tokens per second (specific to large language models).
- Time to first token (TTFT): For generative models, this is the delay between a request arriving and the first token coming back. It shapes how responsive an application feels, which is why it is often a better guide to user experience than total latency.
- Accuracy: The quality of your model’s outputs, rather than of the inference process itself. It is typically expressed as a value between 0 (highly inaccurate) and 1 (highly accurate), or as the equivalent percentage.
For more on what these metrics reveal in production, read What is time to first token (TTFT)? and What time to first token reveals about AI performance.
ML inference challenges
Inference is where AI models deliver their value, but running it in production brings three recurring challenges.
Infrastructure cost
Inference is designed to be fast and efficient, but at production scale it runs on GPU capacity that has to be sized, powered, and kept busy. Idle capacity still costs money, so cost depends heavily on utilization. The goal is to keep hardware fully used, which drives down the cost per inference.
Latency
Latency is the time delay between when an AI system receives an input and generates the output, measured end to end.
Low latency is a common requirement for many applications. For example, mission-critical applications such as autonomous navigation often require real-time inference and, therefore, require lower latency. However, some use cases do not require immediate responses, such as data analytics.
Compatibility
Inference engines implement model operations differently, which can speed up or slow down inference. Those operations are also optimized for specific GPUs. As a result, inference performance depends on how well the engine, the model, and the underlying hardware fit together. Standard model formats and APIs make it easier to move workloads between engines and providers as needs change.
Where does AI inference run
Cost, latency and compatibility come back to the same question: what the model runs on. Two deployment models cover most production inference today, and many teams use both.
Serverless inference
Serverless inference runs a model through an API without provisioning, configuring or operating the GPUs behind it. Capacity is shared and scales with demand, so teams can start in minutes and pay only for what they use. It suits variable traffic, early experimentation, and workloads that can absorb the latency of a shared pool. Read more about serverless inference.
Dedicated inference
Dedicated inference runs the same models on GPU capacity reserved for a single customer. Because that capacity is not shared, performance holds up under sustained load and workloads stay isolated, which matters where data boundaries or sovereignty requirements apply. It suits sustained high-throughput traffic, custom or fine-tuned models, and strict latency targets.
Most teams do not choose once. A common path starts with a serverless endpoint and moves to dedicated capacity once a workload is sustained or customized enough to justify reserving GPUs. Nscale Cloud provides both through OpenAI-compatible APIs, so the capacity behind an endpoint can change without rebuilding the integration around it.
Why is AI inference important?
Inference is how AI delivers value in the real world. It brings together decades of AI discovery into the real world, from gathering data, cleaning it, training the model and optimizing it to provide accurate tangible outcomes. The faster, more efficient and more accurate an AI inference system is, the more impact it has.
Here are some points on why AI inference is important:
- Real-time decision making: Inference allows AI systems the capability to respond to new data in real-time.
- Scalability: A well trained model backed by inference can be deployed at scale across various platforms and applications.
- Cost-effective: Inference is where the cost of running a model is won or lost. Selecting a model with the right trade-offs between performance, latency and compute consumption can reduce cost per inference and make more use cases commercially viable.
- Accelerates innovation: Fast, reliable inference lets teams ship AI features and improve them based on real usage.
Getting started with AI inference
AI inference is where a trained model starts delivering value, turning new data into predictions, classifications, or generated text. How well it performs comes down to latency, throughput, TTFT, and output quality, balanced against cost per inference.
Nscale Inference Endpoints support both serverless and dedicated deployments, so teams can start small and scale up without rebuilding their integration.
Learn more: Explore Inference Endpoints
Published October 8, 2024 | Last updated: October 23 2026
Originally written by Nisha Arya. Updated by Ami Bakhai